Coding Projects

Selected work in genomics, data engineering, and machine learning

Diabetes Classification Case Studies

I developed two machine learning case studies using harmonized continuous glucose monitoring (CGM) data from Glucose-ML. The first evaluated logistic regression, random forest, and XGBoost models for classifying Type 1 diabetes, Type 2 diabetes, prediabetes, and no diabetes across 13 datasets. The second compared single-dataset and multi-dataset training, using repeated experiments and an external test cohort to assess how dataset diversity affects model generalizability.

Python • scikit-learn • Statistical Modeling • Machine Learning
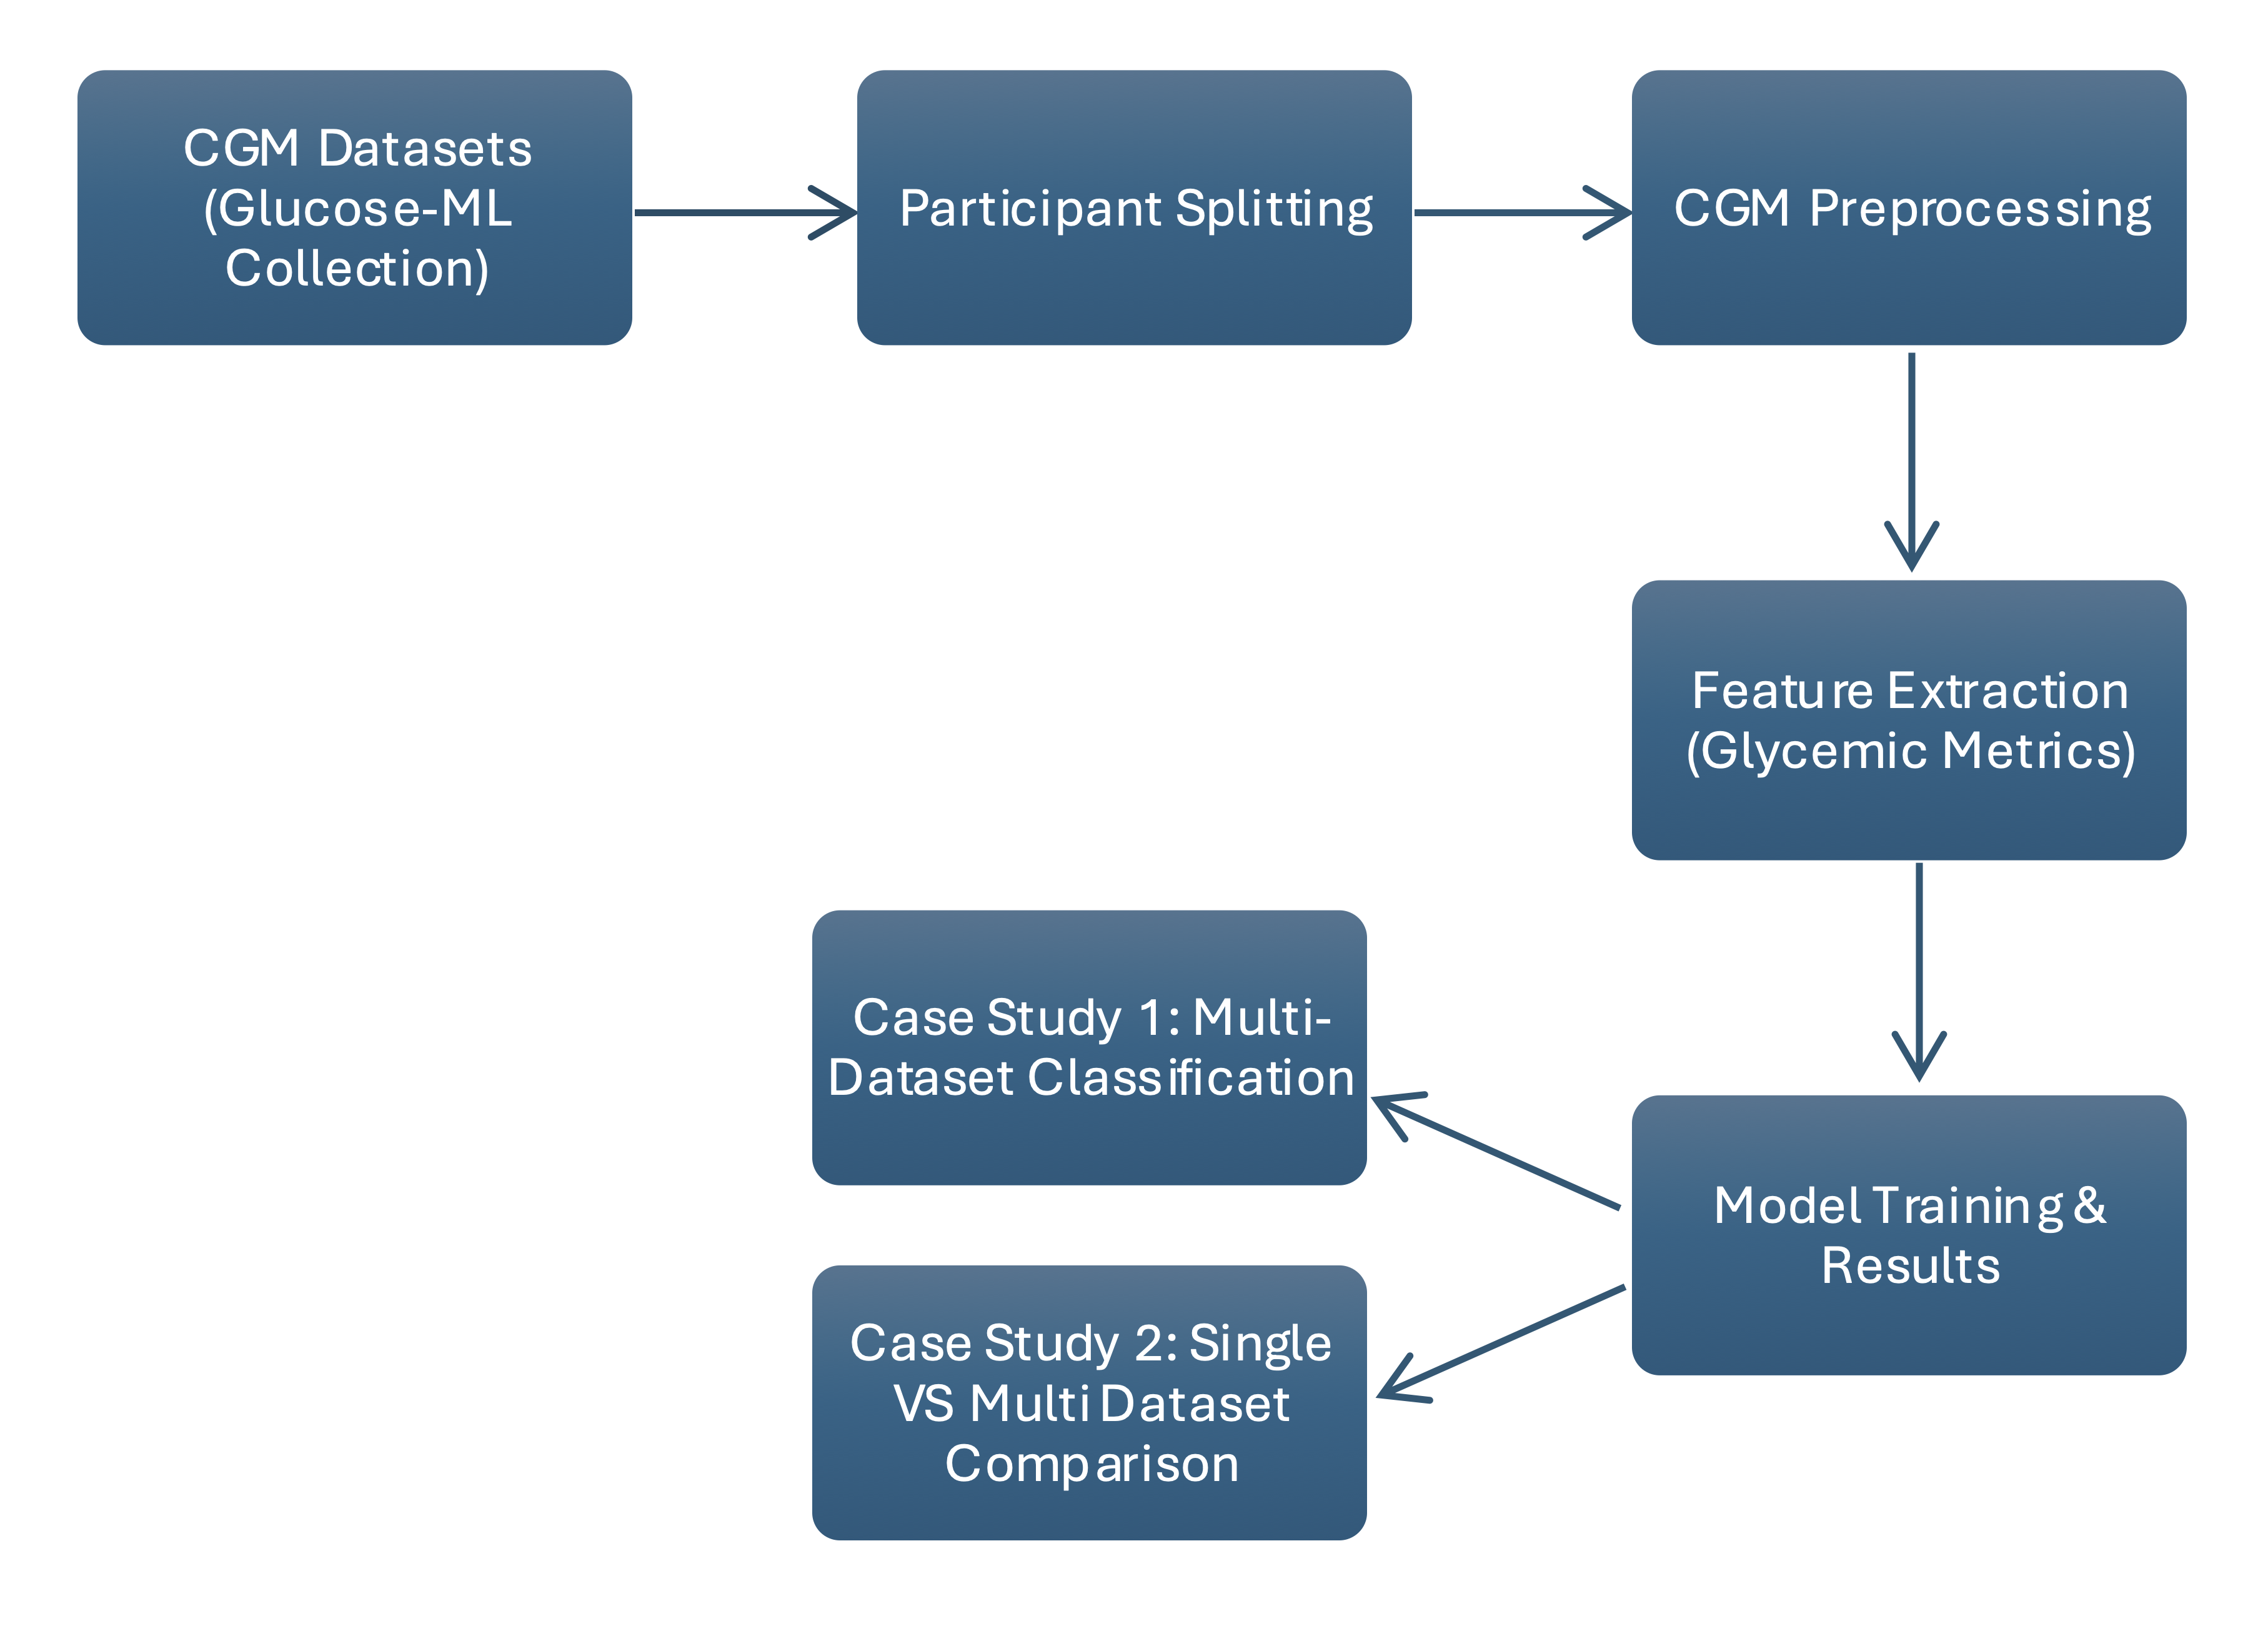
Glucose-ML case studies preview

Glucose-ML Standardization Workflows

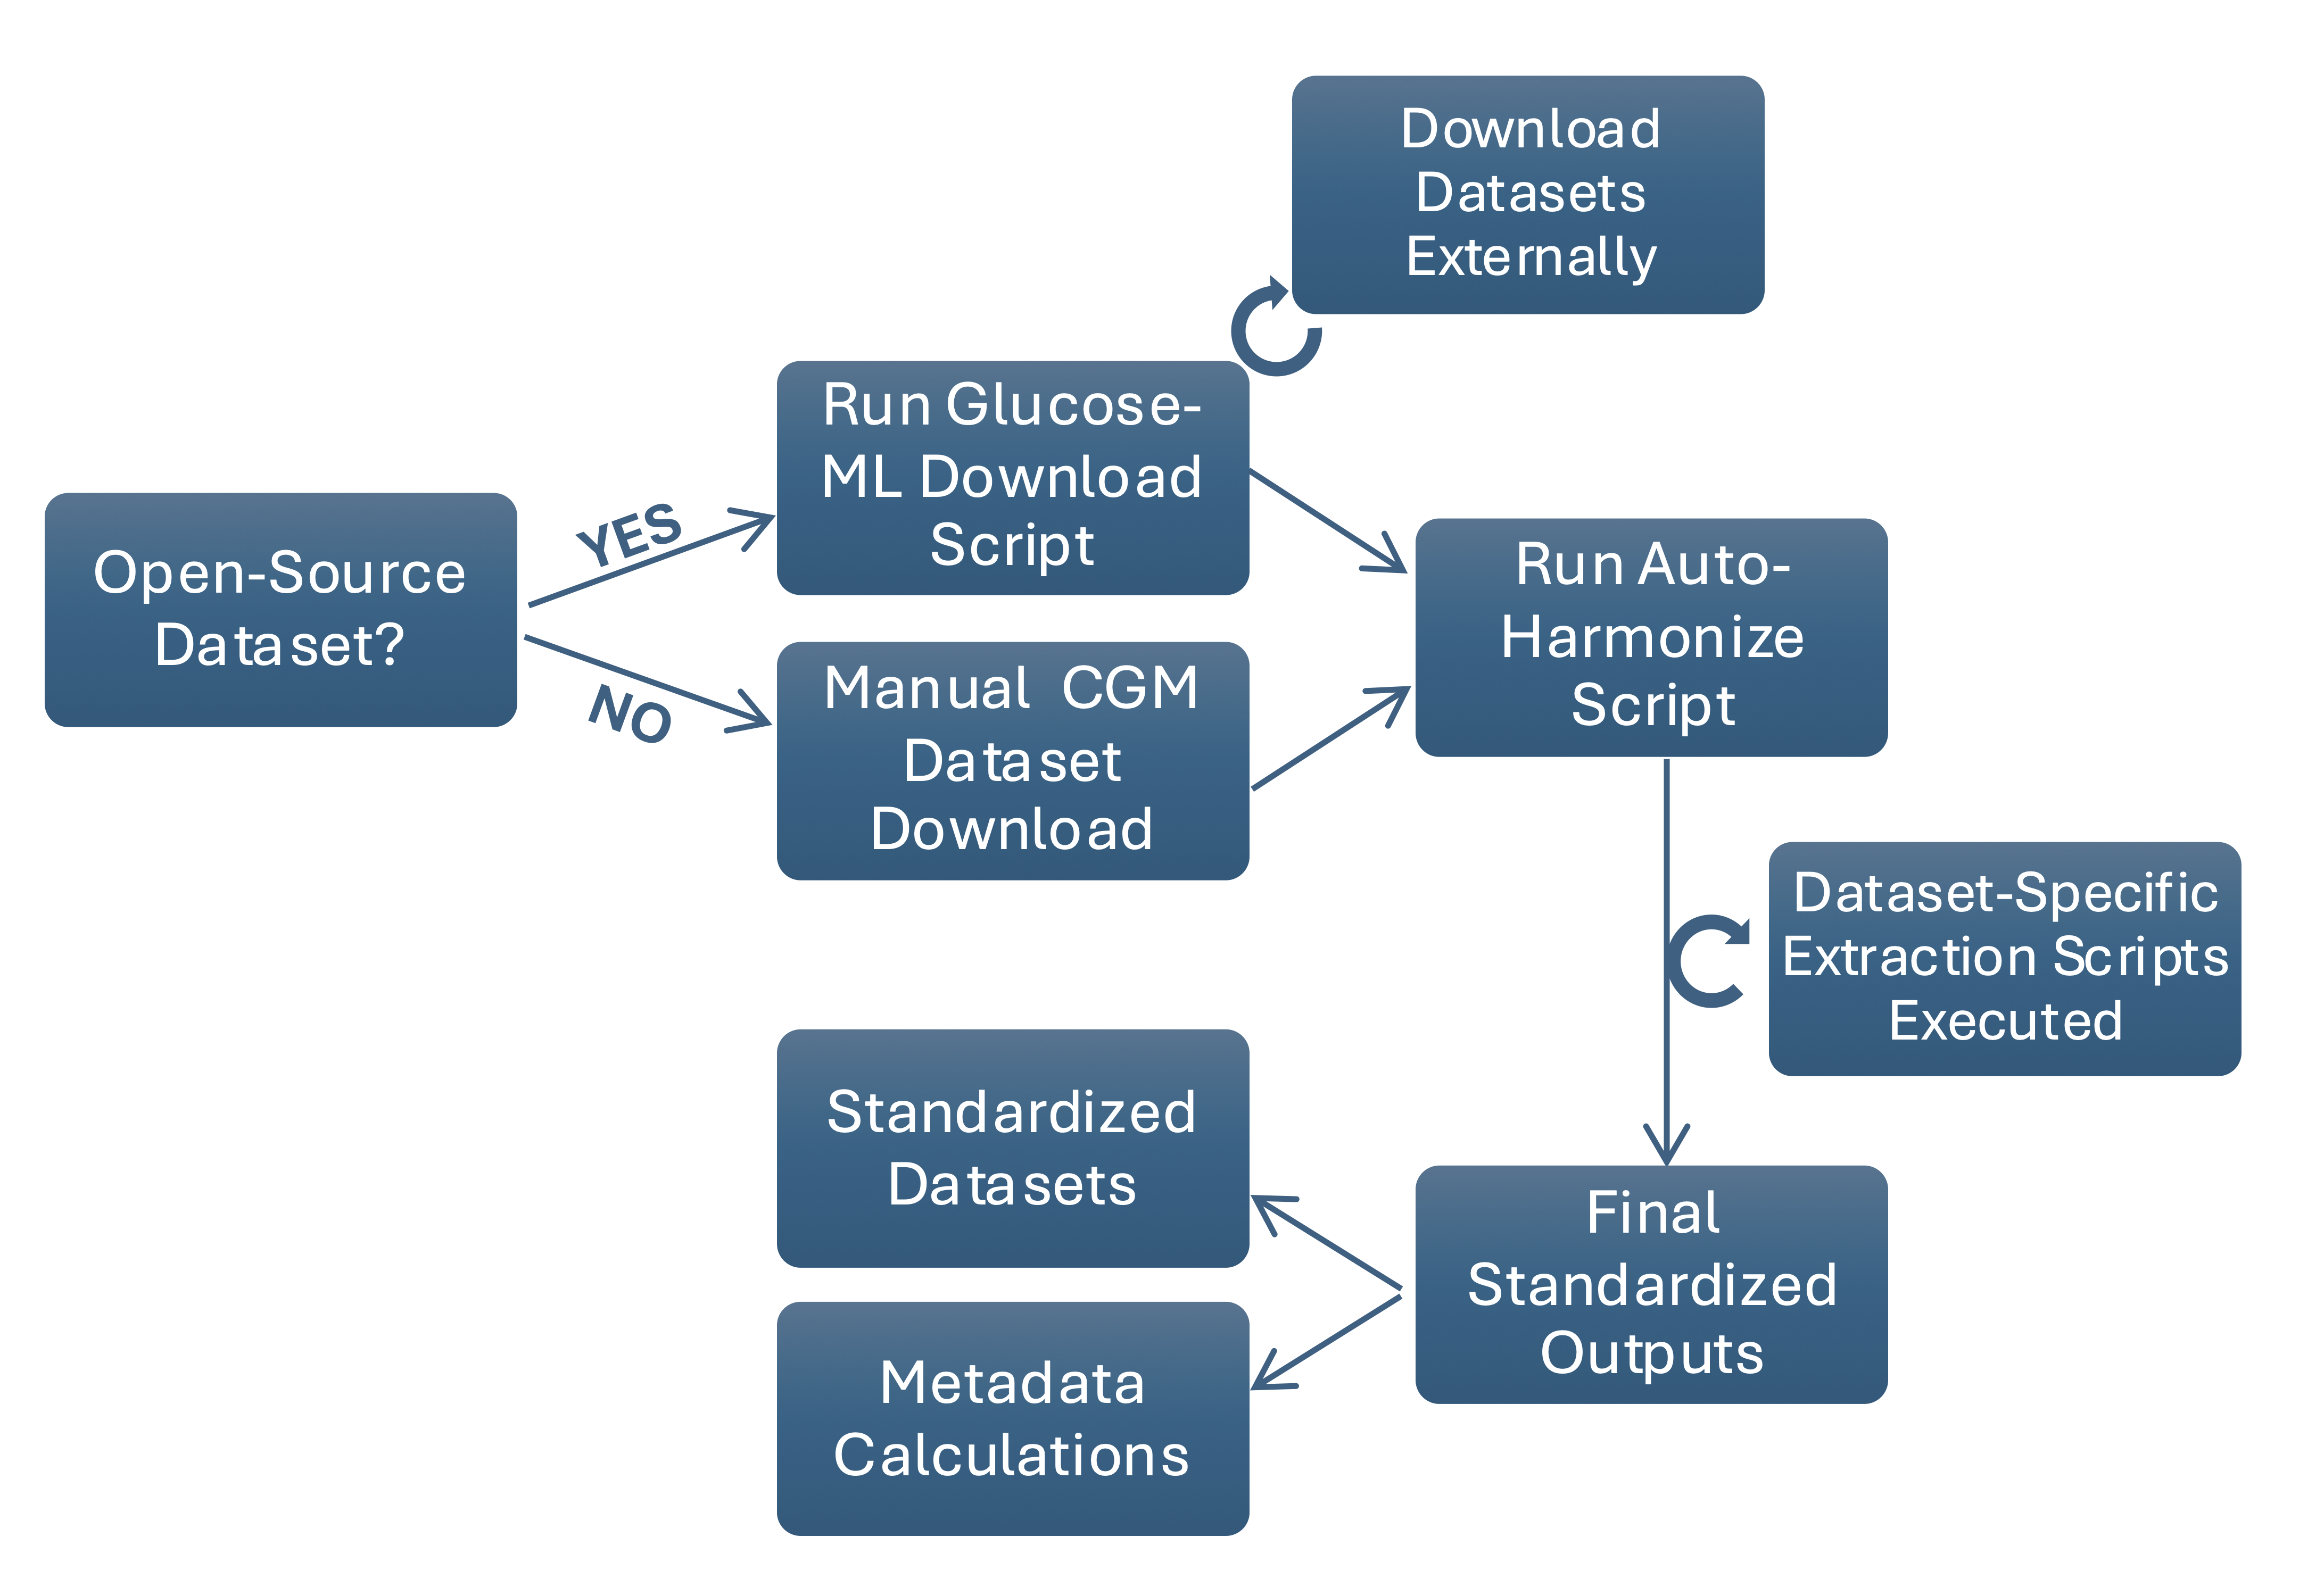
I developed Python and Bash workflows to acquire, validate, and harmonize public CGM datasets for the Glucose-ML collection. The pipelines address differences in file structures, timestamps, glucose units, participant metadata, and data completeness to produce consistent, analysis-ready time series. These reusable tools helped standardize more than 49 million readings from 20+ datasets, supporting reproducible biomedical research and machine learning.

Python • Bash • Data Engineering • Data Harmonization

Glucose-ML standardization workflow preview

CCGP Metadata Bank (In Development)

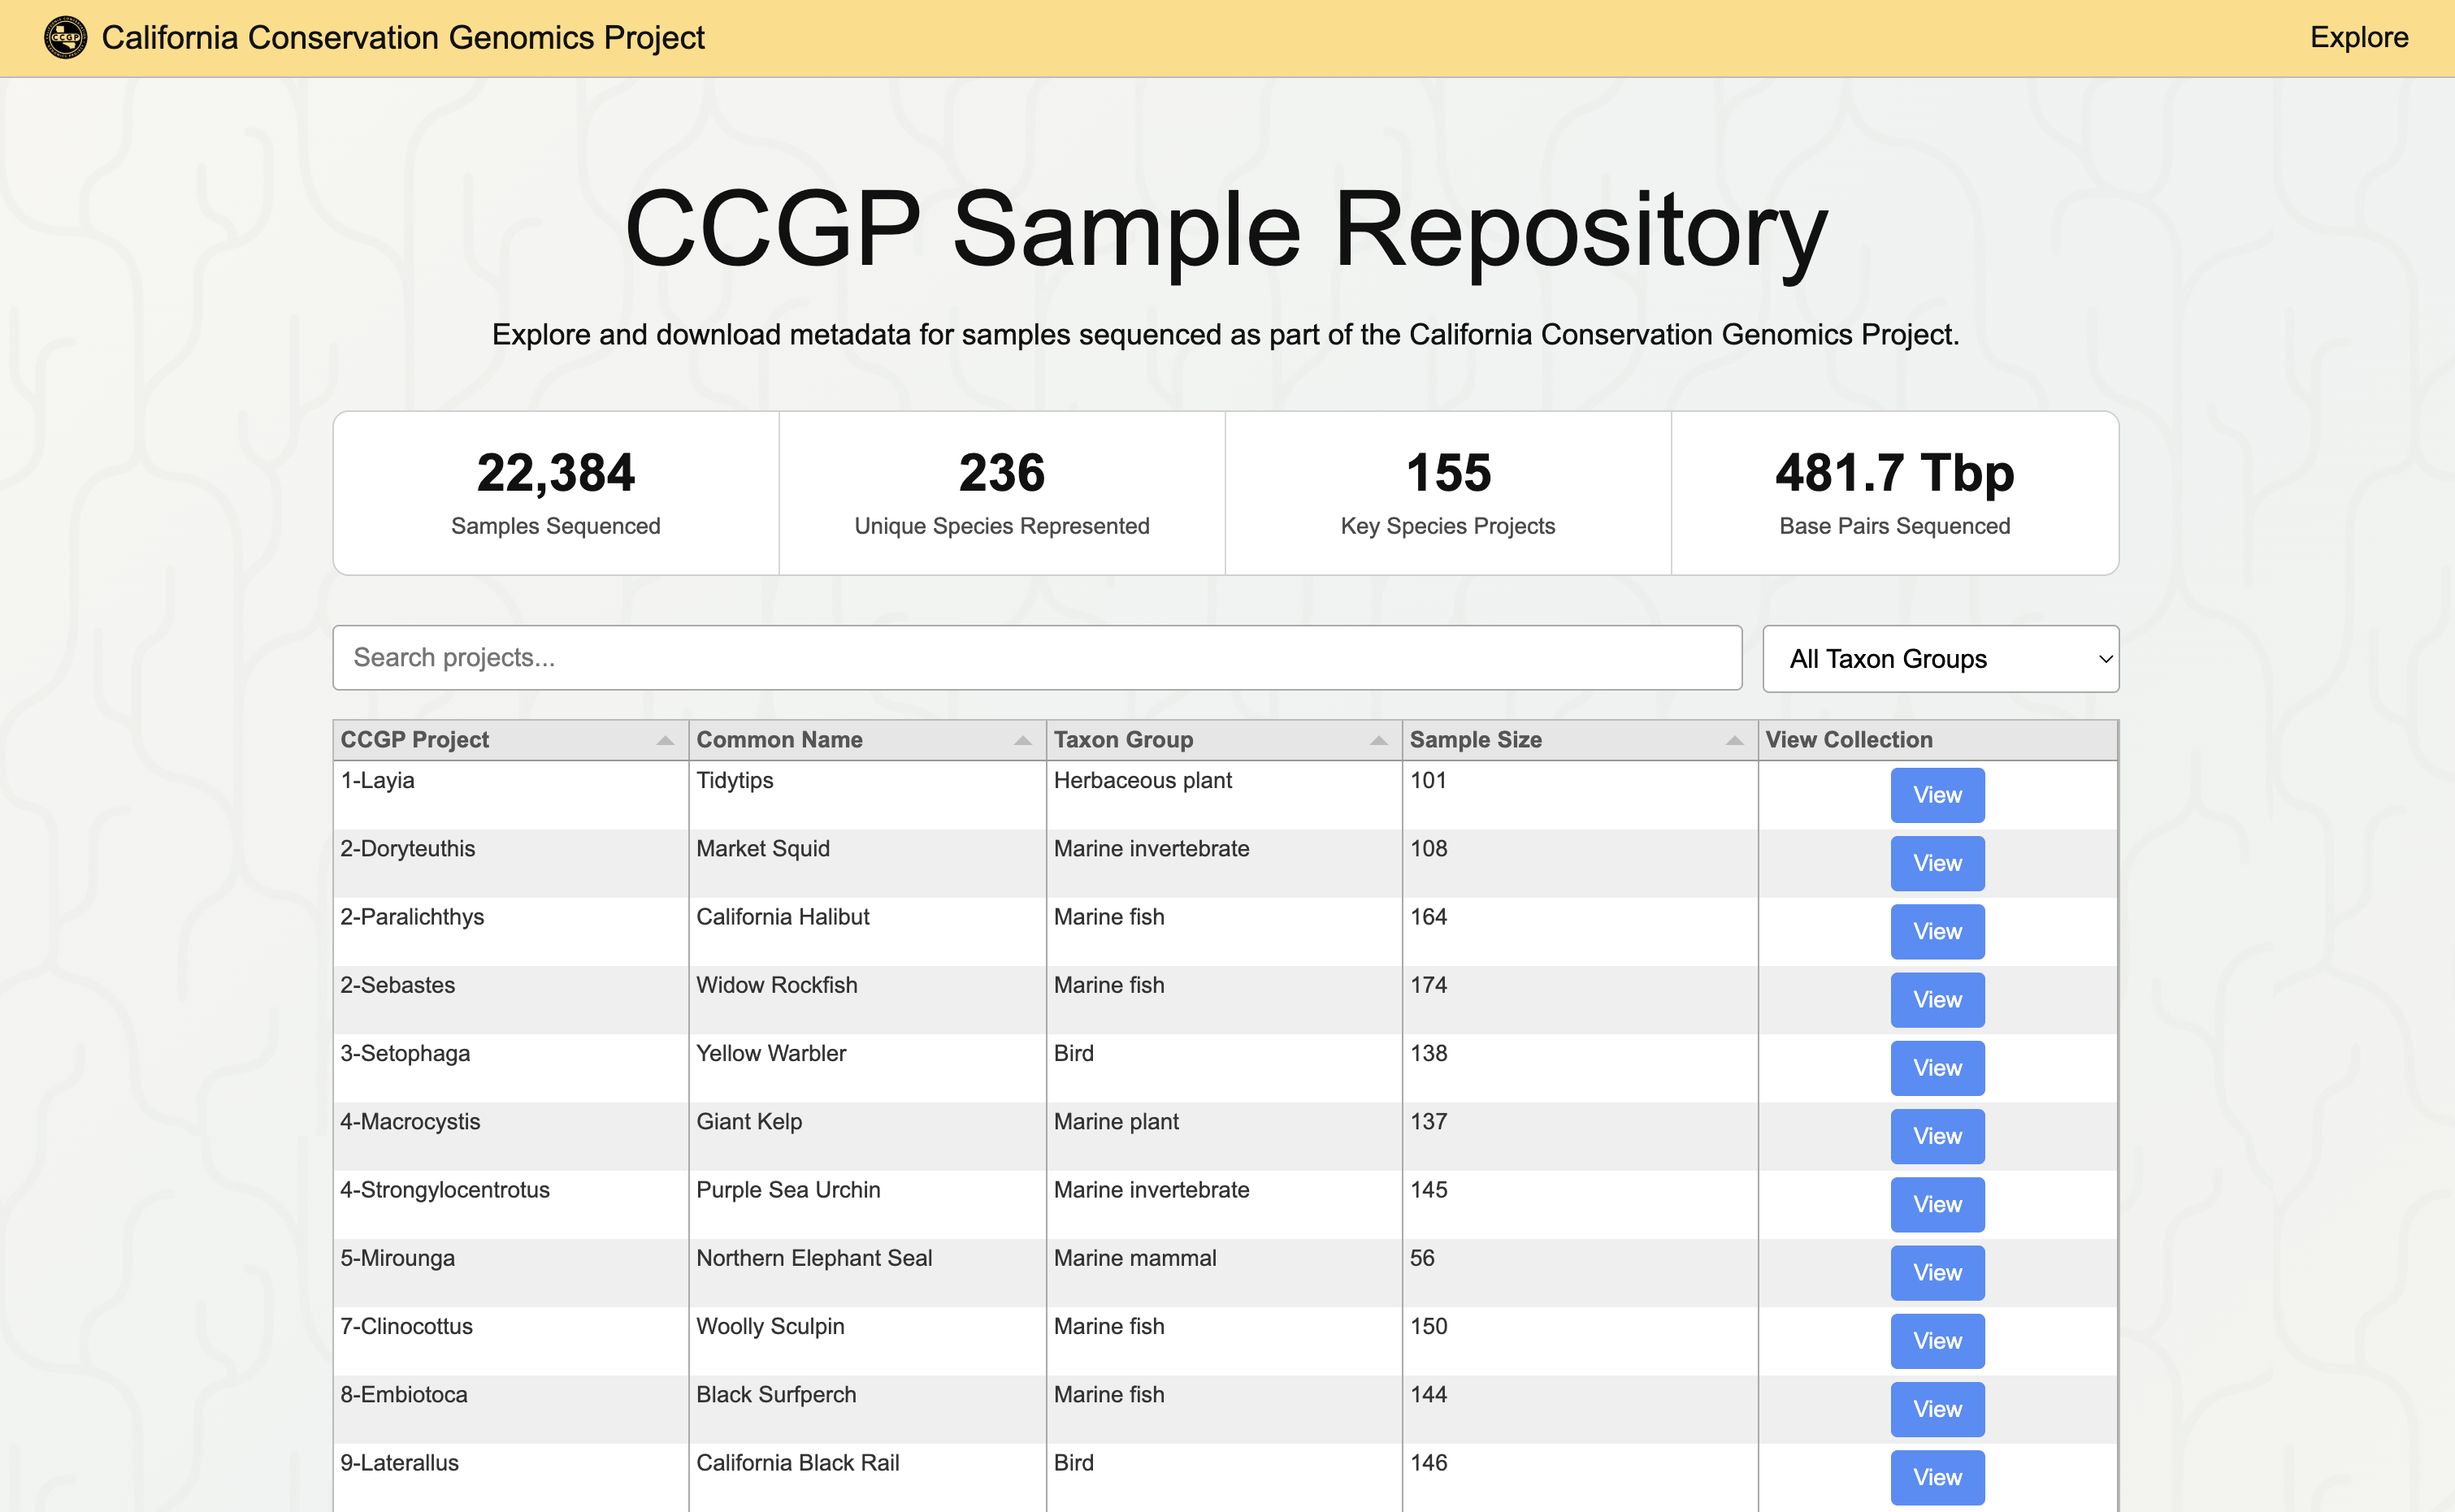
I am leading the development of a public-facing sample repository for the California Conservation Genomics Project. The goal is to make curated genomic sample records easier for researchers to discover and download, building on CCGP's MongoDB sample database. The portal is designed to improve access to standardized metadata across the project's diverse species and sequencing studies.

MongoDB • Web Development • Genomic Data Management

CCGP Metadata Bank

GONE Population Genomics Workflow

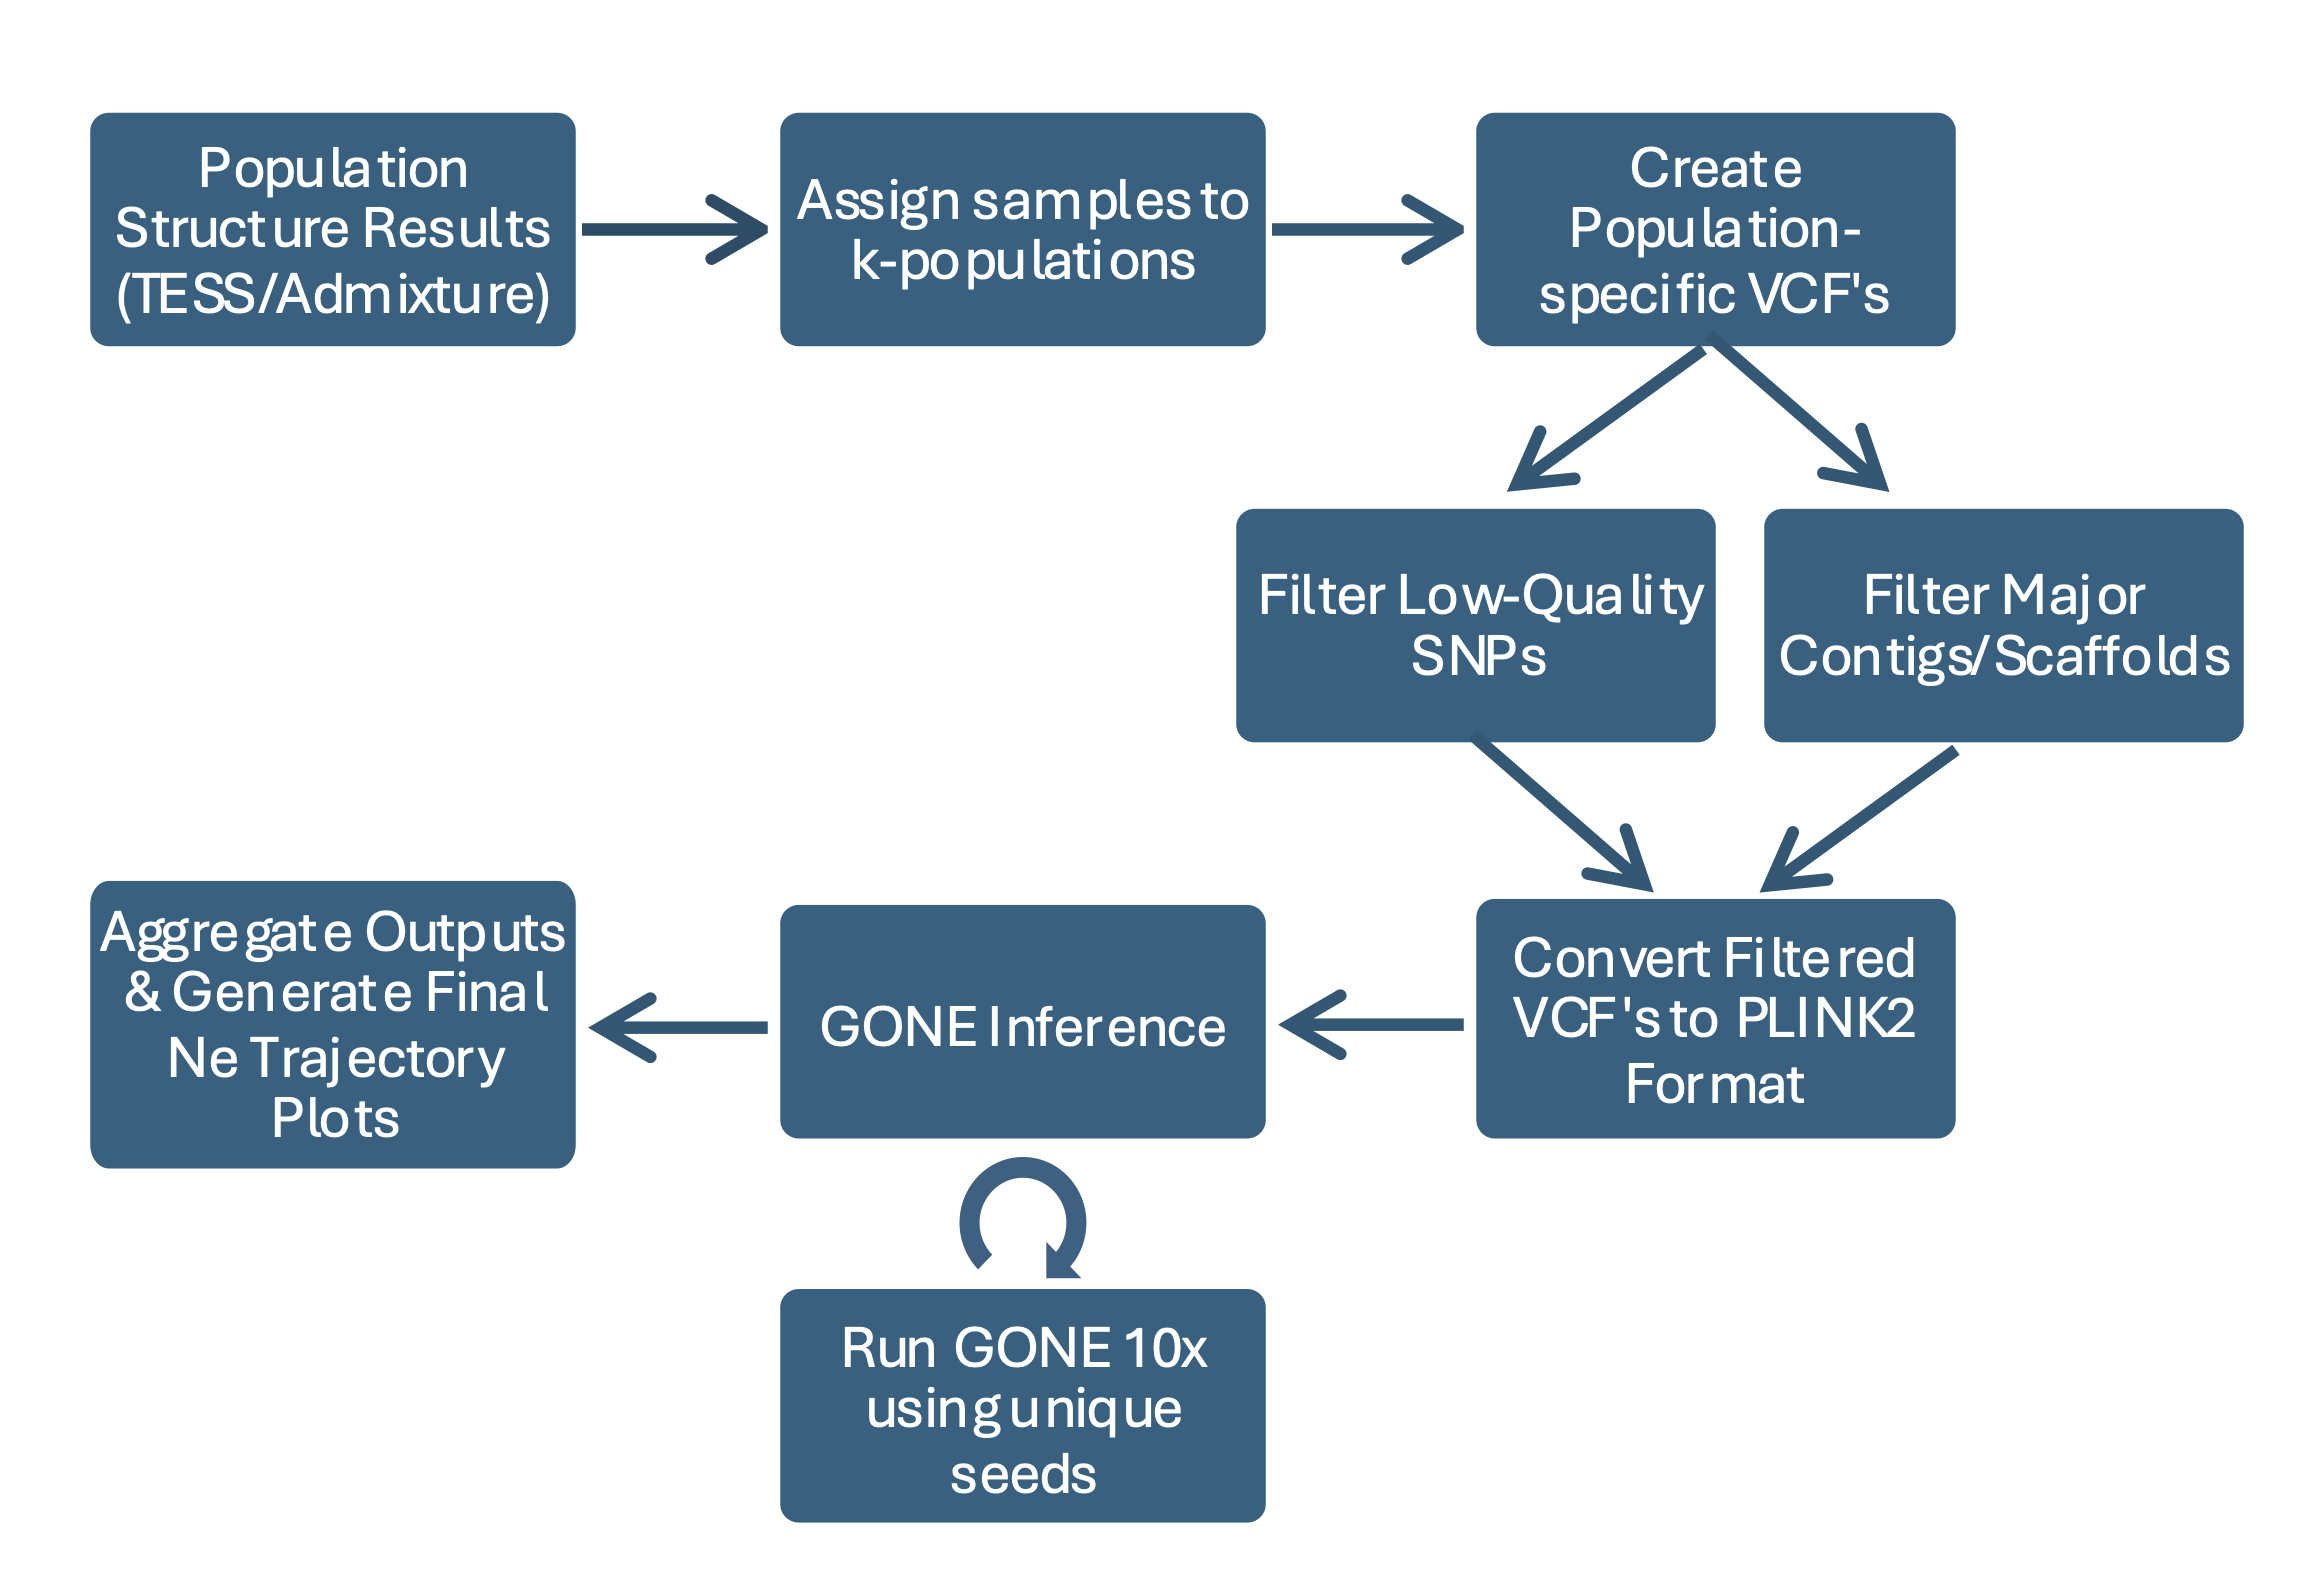
I developed a Snakemake module to estimate recent effective population size across non-model species using GONE, which infers demographic history from linkage disequilibrium patterns in SNP data. The workflow uses population assignments from upstream analyses, applies population-specific variant filtering, and runs replicated analyses. Integrated with the consortium's runs-of-homozygosity and nucleotide-diversity workflows, it supports reproducible population genomics research across 150+ species projects.

Snakemake • GONE • PLINK2 • Python • HPC

GONE workflow preview

Stairway: PAV/MSMC2 Demographic Inference

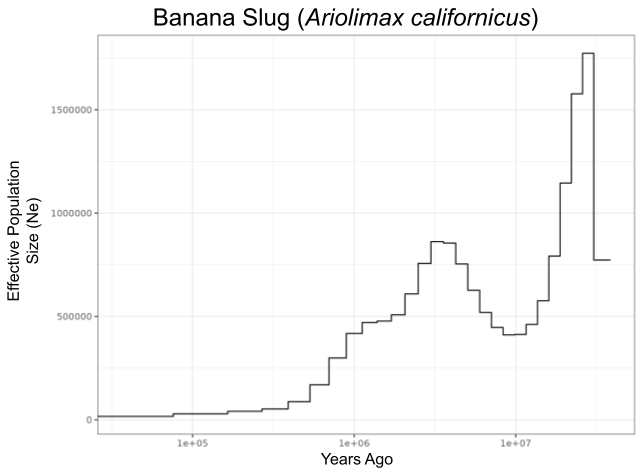
I developed a Snakemake workflow (internally called Stairway) to reconstruct historical effective population size from two phased reference-genome haplotypes. The pipeline uses PAV to identify variants and callable genomic regions, prepares validated inputs for MSMC2, and generates historical population size visualizations. Applied to approximately 100 CCGP species projects, it enables demographic analyses without requiring extensive population-level sequencing data.

Snakemake • PAV • MSMC2 • bcftools • HPC

Stairway workflow preview

NCBI SRA/BioSample Metadata Generator

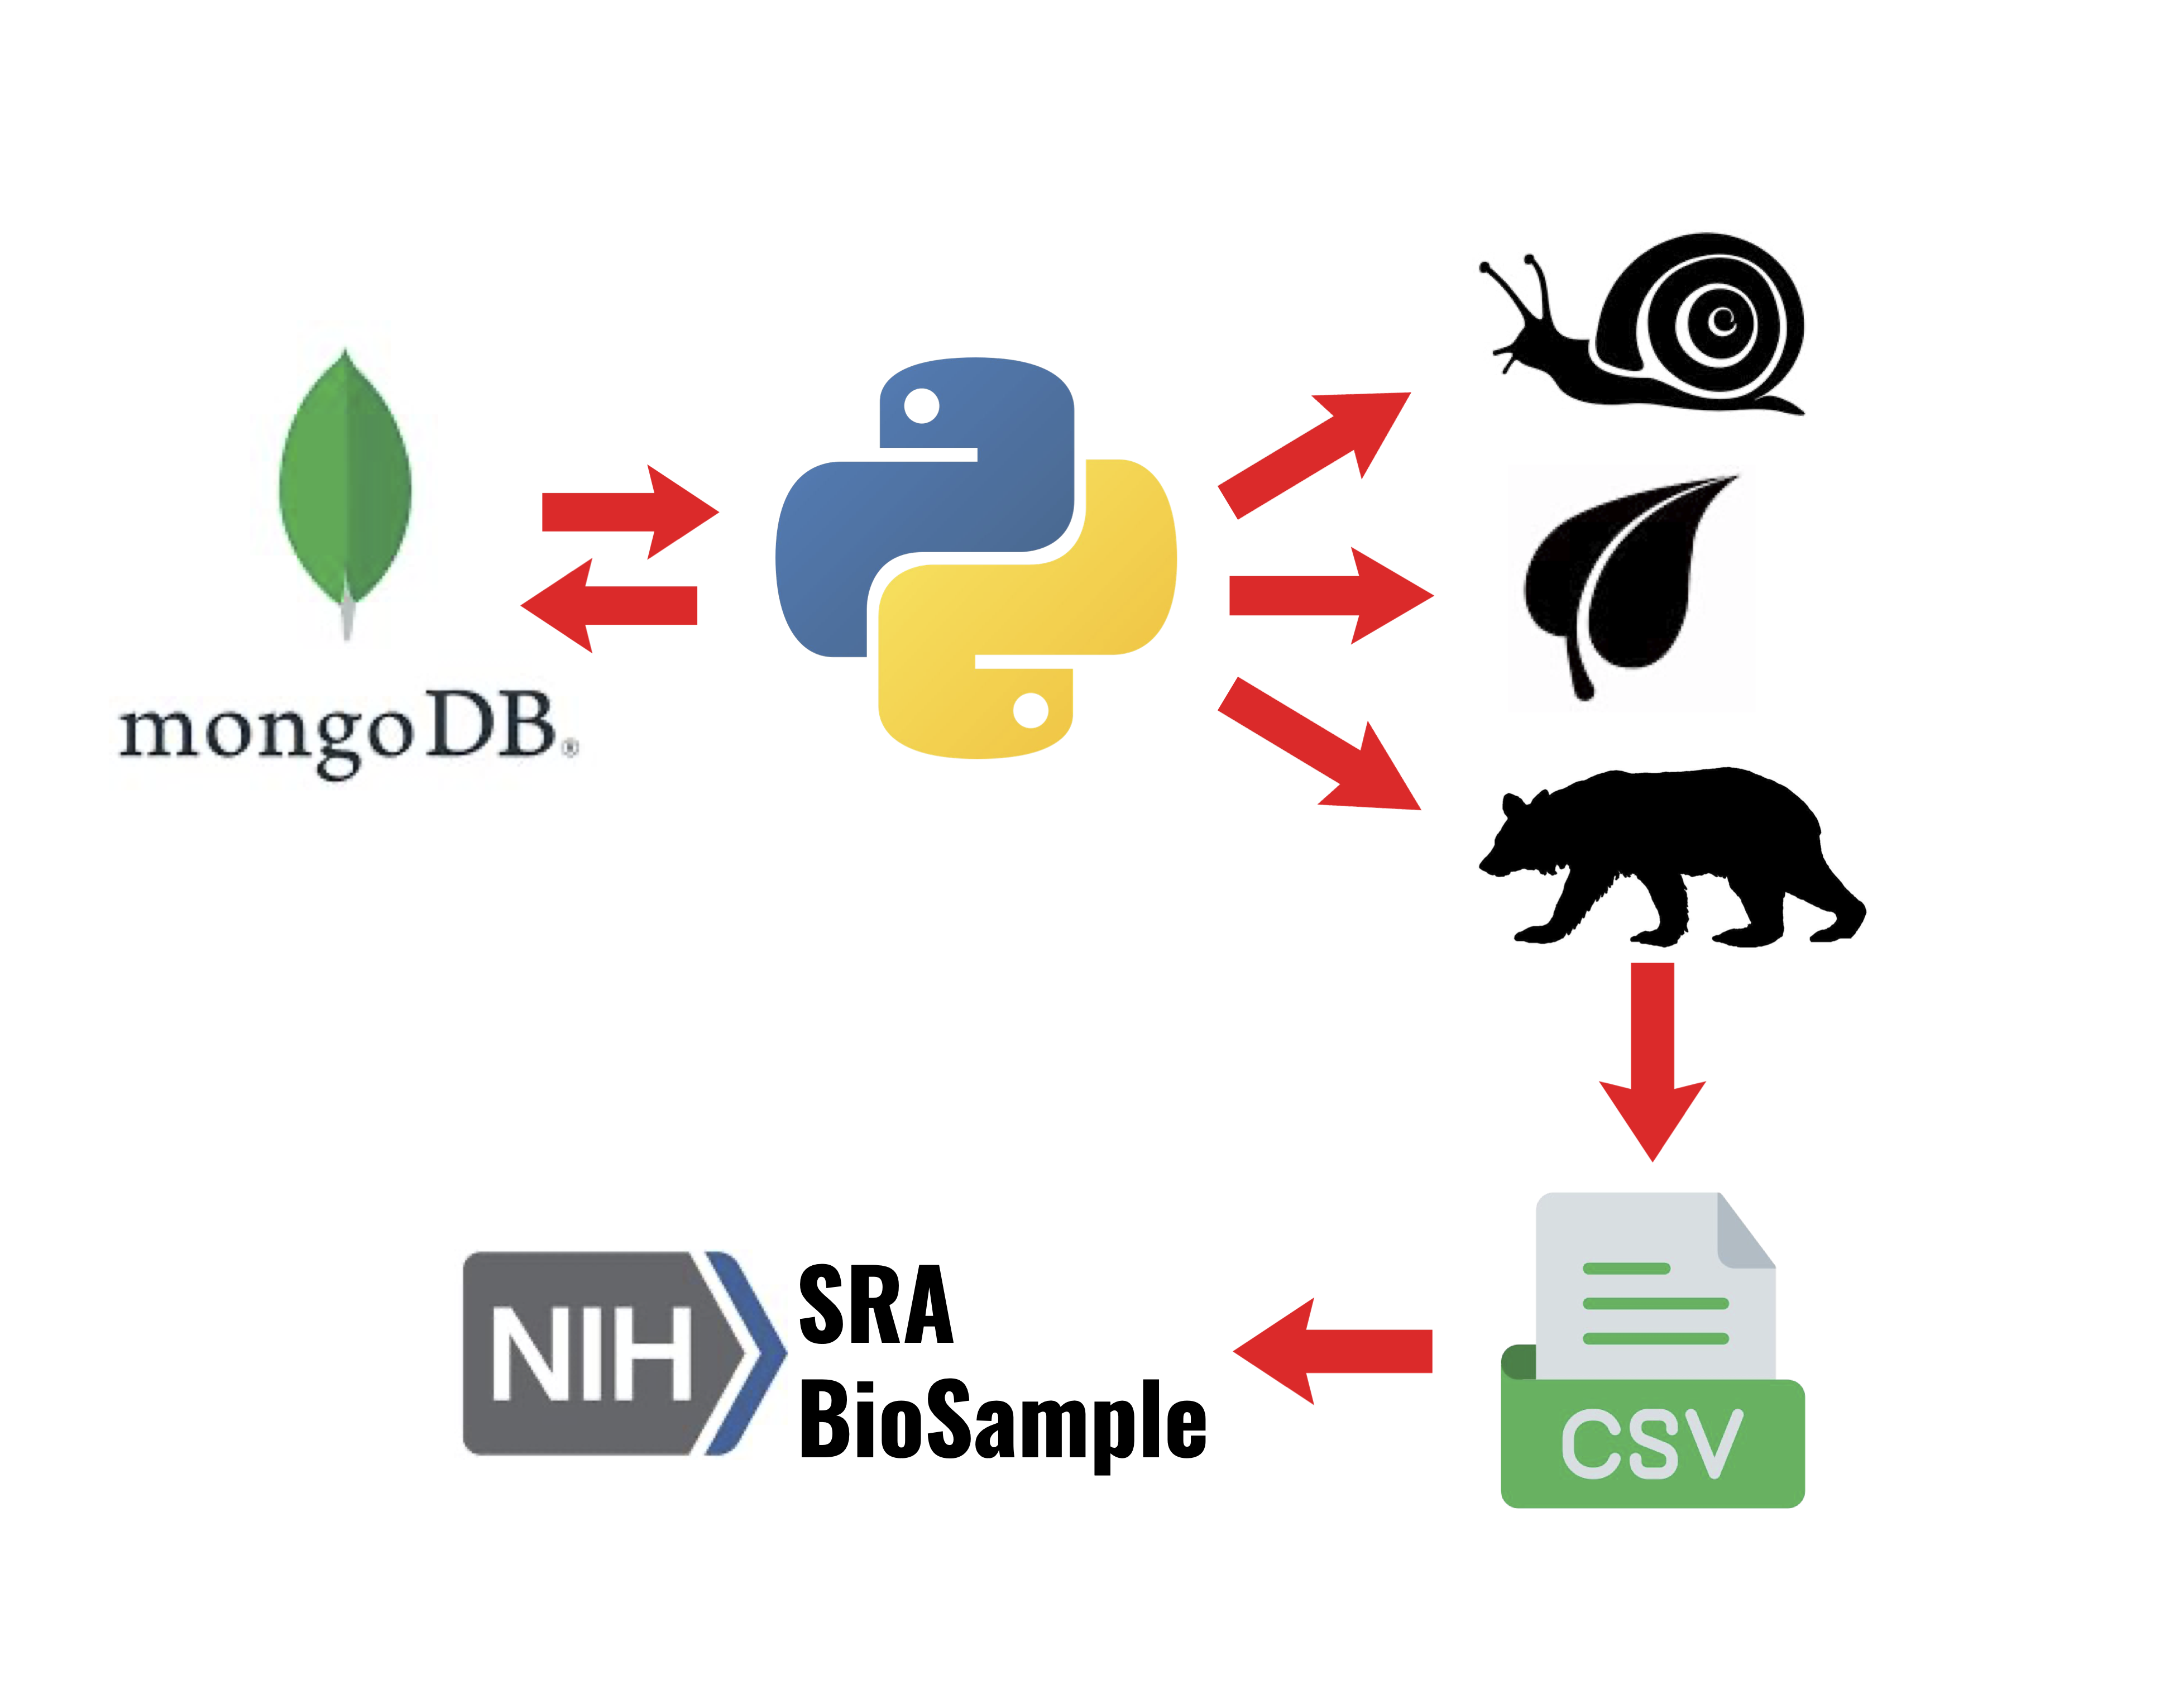
I developed a Python tool that transforms sample metadata from the CCGP MongoDB database into validated submission sheets for NCBI SRA and BioSample. It automates read-pair matching, checks metadata consistency, and produces taxon-specific formats for plant, vertebrate, and invertebrate projects, reducing manual preparation for public genomic data submissions.

Python • MongoDB • NCBI • Metadata Validation